Walk into any San Francisco tech meetup right now and ask engineers what model powers their local backend. Half of them won't say OpenAI or Anthropic. They'll mention DeepSeek, Qwen, or Yi.
That single shift explains why Washington is currently tearing itself apart over how to handle Chinese open-weight AI. When companies like DeepSeek and Alibaba started releasing high-performing model weights to the public for free, they flipped the entire global AI race upside down. Suddenly, anyone with a decent GPU cluster could download, modify, and run frontier-level intelligence without paying an American API provider a dime.
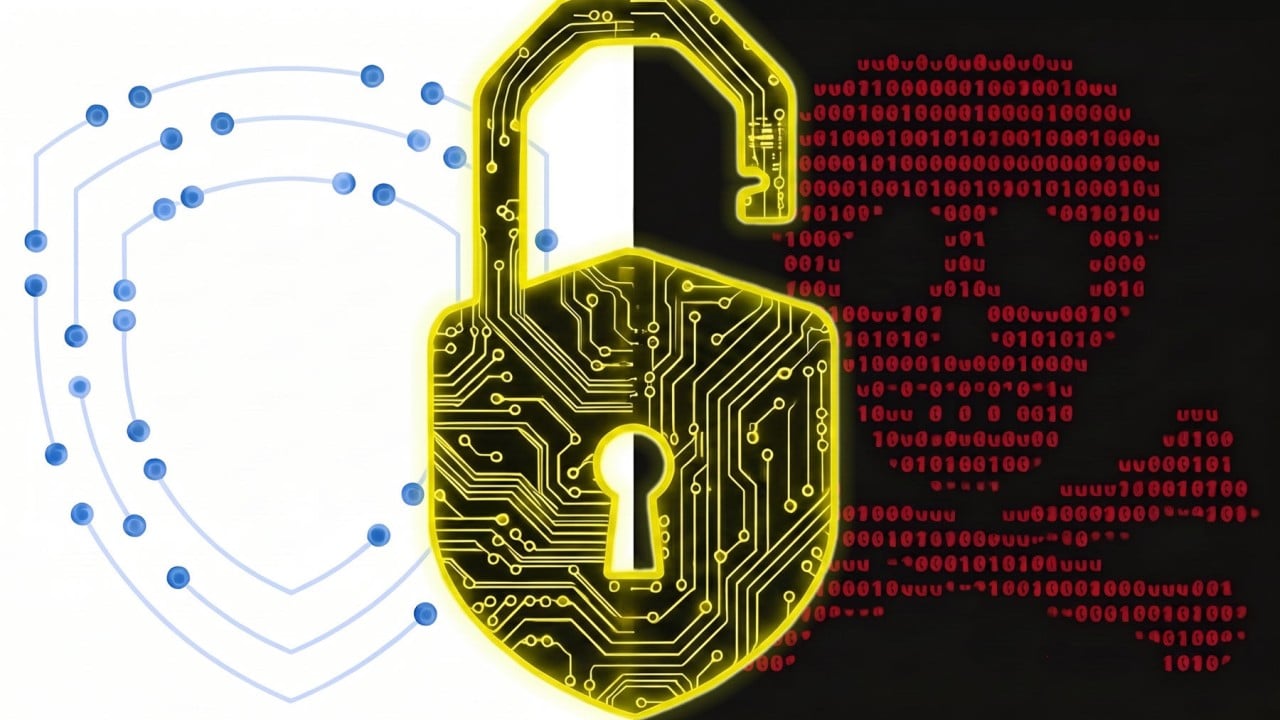
Is this a brilliant defensive shield for the global developer community, or is it a Trojan horse loaded with geopolitical risk? Honestly, the debate gets bogged down in extremes. National security hawks treat every open-source release from Hangzhou or Beijing like a biological weapon. Meanwhile, open-source purists act like code is completely neutral and politics don't exist. Both sides are missing the actual mechanics of how these models work in the real world.
Why China Embraced Open Weights While the US Pulled Back
To understand the panic in Washington, you have to look at the business math. American tech giants like OpenAI and Google spent billions on compute, so they locked their best models behind paid APIs to recoup the cash. Even Meta, long the champion of open weights with its Llama series, has faced intense pressure over safety and monetization as training runs get wildly expensive.
China took a completely different route. Facing strict US export controls on high-end Nvidia chips like the H100 and B200, Chinese labs couldn't easily win a brute-force compute war. Instead, they optimized for efficiency and distribution.
Take DeepSeek. When the Hangzhou-based lab dropped DeepSeek-R1 and DeepSeek-V3, they didn't just match Western frontier performance on math and coding benchmarks. They did it at a fraction of the reported training cost using clever architectural tricks like Mixture-of-Experts (MoE) and Multi-head Latent Attention. By releasing the weights under permissive licenses like MIT or Apache 2.0, they immediately captured global mindshare.
Alibaba did the exact same thing with its Qwen family. If you look at the Hugging Face leaderboards today, Qwen models dominate the open-source rankings across almost every parameter size, from tiny 0.5B models that run on a smartphone to massive 72B beasts.
When Chinese labs give away their best tech, they accomplish three things simultaneously:
- They commoditize the core intelligence layer, undercutting the business models of closed US labs.
- They force global developers to build their software pipelines around Chinese model architectures.
- They bypass Western app store bans and cloud restrictions because developers host the code themselves.
It's a classic asymmetric strategy. If you can't beat the incumbent on hardware supply, make their software profit margins disappear.
The Weapon Argument Why Security Hawks Are Losing Sleep
So why do policymakers call these models a weapon? The concerns aren't totally imaginary, even if they sometimes get exaggerated on cable news.
First, there's the dual-use problem. Open weights mean the safety guardrails—the fine-tuning that stops a model from explaining how to synthesize dangerous pathogens or write polymorphic malware—can be stripped out in about twenty minutes. Researchers at organizations like the Center for AI Safety have demonstrated repeatedly that fine-tuning an open-weight model on a small dataset of harmful examples completely erases its refusal training. Once the weights are out on the internet, you can't recall them.
Second, there's the subtle issue of ideological alignment and censorship. Out of the box, models trained inside China comply with strict domestic regulations enforced by the Cyberspace Administration of China (CAC). Ask a raw Chinese model about Tiananmen Square, Taiwan, or Xinjiang, and it'll either dodge the question or recite official state talking points.
Security analysts worry about what happens when millions of Western apps, customer service bots, and educational tools quietly integrate these models under the hood. Even if a developer removes the obvious political censorship, subtle framing biases baked into the pre-training data remain. You don't need a dramatic cyberattack to influence public opinion; you just need a slightly skewed autocomplete engine running on millions of devices.
Then there's the data and telemetry angle. Downloading weights from Hugging Face doesn't automatically send your data back to Beijing—that's a common myth. If you run Qwen locally on your own servers, no packets leave your network. However, many developers don't have the hardware to host large models, so they use cheap API endpoints hosted directly in China. In those cases, your prompts, proprietary code, and user data fall straight under China's National Intelligence Law, which compels domestic companies to cooperate with state intelligence agencies.
The Armour Argument Why Open Weights Protect Everyone
If you talk to cybersecurity experts and independent AI researchers, you'll hear the exact opposite framing. To them, widespread access to strong open-weight models isn't a weapon—it's essential armour.
Think about what happens if only three or four massive corporations in California control all advanced AI. That kind of concentration creates a terrifying single point of failure. If one provider suffers an outage, changes its terms of service overnight, or decides to quietly alter how its model answers sensitive questions, millions of businesses are stuck.
Open weights break that monopoly. When a hospital, a European bank, or a small defense contractor downloads a model and runs it inside an air-gapped environment, they have total sovereignty over their stack. Nobody can spy on their prompts. Nobody can throttle their API access. Nobody can raise prices by 300% next quarter.
More importantly, transparency actually improves security. When thousands of independent researchers can inspect the weights, probe the model's activation layers, and test its failure modes, vulnerabilities get found and patched fast. Closed models rely on "security through obscurity," meaning outsiders just have to trust the vendor's marketing blog when they claim a model is safe.
During testimony before the US Senate and in various policy papers, technologists like Yann LeCun have argued that shutting down open-weight AI won't stop bad actors—it'll just ensure that only well-funded state adversaries and giant monopolies have access to the strongest tools, leaving defenders blind.
What Developers Actually Experience on the Ground
Step away from the policy think tanks and talk to engineers actually shipping products, and the picture gets much more practical. Most CTOs aren't thinking about geopolitics when they pick a model; they're looking at latency, token costs, and benchmark reliability.
I've watched dozens of startups migrate away from proprietary US APIs over the past year. The reason is simple. If you're processing millions of customer support tickets or parsing massive legal PDFs, paying per token adds up fast. Hosting a quantized version of Qwen or DeepSeek on rented cloud GPUs cuts inference costs by 70% to 80% while giving you predictable latency.
Still, deploying Chinese open-weight models in a Western enterprise comes with real friction that nobody puts in the press releases:
- Compliance headaches. Enterprise clients—especially in healthcare, finance, and government contracting—now include strict vendor questionnaires asking about the origin of every AI weight in your pipeline. Using a model trained in China can instantly disqualify you from certain US federal contracts or European public-sector tenders.
- Hidden refusal triggers. Even when you aren't asking political questions, aggressive safety filters baked into the base weights sometimes trigger false positives on completely benign business queries, forcing engineers to spend weeks doing custom post-training to make the model behave normally.
- License fine print. Not every "open" model is truly open source. While DeepSeek embraced the standard MIT license, other labs use custom community licenses with strict monthly active user caps or weird redistribution clauses that corporate legal teams hate.
Can You Actually Ban Open-Weight AI?
Some lawmakers in Washington have floated the idea of restricting Americans from downloading or using Chinese open-weight models, or using export controls to block foreign labs from publishing weights online.
Frankly, anyone who understands how the internet works knows that's a fantasy.
Model weights are just giant files of floating-point numbers—usually anywhere from a few gigabytes to a few hundred gigabytes. Once a lab uploads those files to a server in Hong Kong, Singapore, or Zurich, they're mirrored across BitTorrent, IPFS, and thousands of private repositories within hours. Trying to ban open weights is like trying to ban encryption or outlawing a specific prime number. You can pass a law making it illegal for federal agencies to use them, which is already happening, but you cannot stop independent developers from downloading math.
Trying to build a digital wall around US developers would actually backfire horribly. If American engineers are legally barred from studying and building on top of the best open models while developers in Europe, India, and Southeast Asia use them freely, US startups will quickly fall behind on cost and iteration speed.
How to Navigate This Mess Without Getting Burned
If you're building software, managing IT infrastructure, or advising leadership on AI adoption, you don't need to pick a side in a geopolitical shouting match. You just need smart engineering hygiene.
Start by separating the model weights from the inference infrastructure. Never send sensitive company data, customer PII, or proprietary source code to an API endpoint hosted inside China—or any jurisdiction where data privacy laws don't protect your business. If you want to use Qwen or DeepSeek, download the weights from a verified repository, check the SHA-256 hashes to ensure the files haven't been tampered with, and host them on your own infrastructure in the US or Europe.
Next, treat open weights like any other third-party open-source dependency. You wouldn't drop a random npm package into production without running security scans, and you shouldn't deploy raw model weights without running your own evaluation suite. Test the model specifically for prompt injection vulnerabilities, weird refusal behaviors, and domain-specific accuracy before letting it touch customer data.
Finally, keep your architecture modular. Abstraction layers like LiteLLM or standard OpenAI-compatible endpoints make it trivial to swap models in and out. If regulations tighten tomorrow, or if an American lab drops a better open model next month, you should be able to switch your backend with a single config change rather than rewriting your entire application.
The debate over whether Chinese open-weight AI is a weapon or armour isn't going away anytime soon. Washington will keep drafting export rules, and labs in Hangzhou and Beijing will keep dropping free, hyper-efficient models onto Hugging Face. Stop waiting for politicians to settle the argument—lock down your hosting environment, audit your weights, and build your stack so you aren't trapped by any single vendor or country.